
hhlee
2026-09-09 21:22:53
Behind
Mission Ready: Setting Up the Ultimate Dev & Ops Workspace for Our Secret Agents
🤔
Smart Token-Saving Hacks for AI Agents (Without Losing the Magic)
Must be nice if your company has an endless budget for AI tokens, but for a hungry startup like us? Token cost-efficiency (a.k.a. the terrifying monthly bill) i...
🤔
Mission Ready: Setting Up the Ultimate Dev & Ops Workspace for Our Secret Agents
At Stew, we're sharing how we set up and utilize our environment for agentic coding. The AI landscape moves at breakneck speed—our own workflows shift dramatica...
🗞️
[Update] Give Stock and Uploaded Photos an AI Makeover with 'Generative Edit'
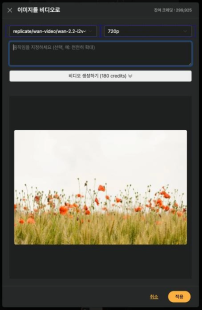
You can now refine and reuse the images you already have—no need to toss them out and start over. With the newly added 'Generate Edit' feature, the image curren...
🎓
Why You Pick a Shorts Template, Make Three Videos, Then Never Use It Again
Search for Shorts templates, and you’ll find an endless supply of free options. But after downloading one and making about three videos, many creators find them...
🎓
Automating shorts is easy—getting them consistently great every time is the real challenge
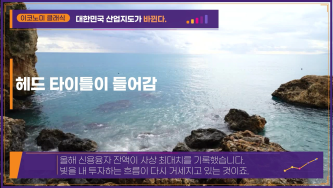
If you search for shorts automation, you’ll find endless workflow tutorials that promise everything at once: script generation, images, voiceover, even upload. ...
🎓
Before You Pick an AI Video Editor, Decide *What* You Actually Want to Make
When you read those “Top 5 AI video makers” listicles, they usually bundle all the trendy tools together, compare pros and cons, and highlight key features.But ...
🤔
Before you get a quote for one AI video, ask yourself this: "How many times will I want to repeat this?"
The first message we usually get from people asking about AI video outsourcing is almost always the same. It all boils down to one question: “How much is it?” I...
📣
How a Franchise Café Automated Its Digital Signage Videos (and Saved a Lot of Time)
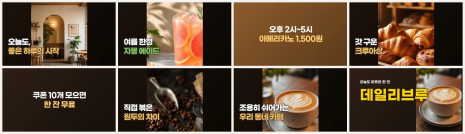
Running Videostew has given us a front-row seat to the challenges faced by potential customers across all kinds of industries.And there’s one topic that always ...

At Stew, we're sharing how we set up and utilize our environment for agentic coding. The AI landscape moves at breakneck speed—our own workflows shift dramatically every 3 to 6 months—so this post might have a short shelf life. Still, assuming the core LLM paradigm doesn't undergo a seismic shift, our experience should be pretty handy. Think of this as our time capsule: how we build in September 2026.
The key shift? We no longer treat AI agents as just another tool in the belt; they are the starting point and the end interface for nearly everything we do. Everything we work on is wired so AI can access and interact with it—from dev and testing to docs, scoped DB access, logging, monitoring, and even customer support. Setting up an ecosystem where the AI can be assigned tasks and orchestrate them on demand has become our top priority.
Remote Dev Servers & Running the CLI
We keep our codebase and CLI tools on a dedicated dev server, remoting in via SSH from our laptops or even mobile devices. Access to dev servers and internal services is secured through a Tailscale mesh network. This untethers us from any single physical machine, letting us jump into the exact same repo and runtime from anywhere. The biggest win? We run Claude Code (claude) or Codex CLI (codex) directly on the server and instantly see results in the dev environment. Plus, with a 24/7 server running, setting up scheduled jobs, repetitive tasks, and full automation pipelines is a breeze.
Letting the Agent Take the Wheel
Bypassing permission prompts to execute commands continuously is affectionately known as "YOLO mode." It's an absolute game-changer in a remote dev environment for low-risk, well-scoped tasks like repetitive searches, running test suites, or digging through logs at warp speed.
Of course, going full YOLO drastically widens the agent's blast radius. If it has access to production servers or credentials, a single slip-up can get spicy real fast. That's why we install proper guardrails: hooks that block sensitive files, mandatory confirmations before touching AWS, and strictly locked-down Cloudflare credentials. Streamlining approvals doesn't mean giving the AI free rein to burn down the house—it’s all about fast iteration with smart safety nets.
Supercharging File Search in Claude
While we might not type out exact file names manually as often as we used to, referencing files accurately is still a massive deal. In my day-to-day workflow, Codex has always been pretty spot-on with short, intuitive path suggestions. Claude’s default file search, on the other hand? Let’s just say it left me tapping my desk in frustration. To fix this, I set up a custom script for `fileSuggestion` inside `.claude/settings.json`.
This little tweak uses `git ls-files` to search only tracked files, giving priority to file name prefixes and shorter, cleaner paths. If you haven't typed a query yet, it smartly suggests recently modified files first. It’s vastly faster at pulling up project files than the default lookup! The catch? Untracked files won't show up, and it relies on external tools like `fzf`—but the speed boost is totally worth it.
Locking Down Sensitive Credentials (No Leaks Allowed!)
Running in bypass or "YOLO mode" lets your AI agent roam free across your codebase. Convenience? Absolutely. Security risk? You bet. If a `.env` file packed with production secrets sneaks into the context window, it’s game over. That’s why we run a strict two-tier security perimeter to keep our credentials safe.
First, we lay down the law in the global guidelines: the agent is strictly forbidden from reading or outputting `.env` files, AWS credentials, Cloudflare configs, SSH private keys, or token vaults. Files like `.env*`, `.aws/credentials`, `.cloudflared`, `.npmrc`, and `auth.json` are completely off-limits. If values are needed, humans check them—the agent only gets to touch non-sensitive identity lookups or public info.
Here’s the thing, though: tell an AI not to touch something, and when it hits a wall, it will often try to read that `.env` file anyway! That’s why you can’t rely on polite prompts alone—you need mechanical guardrails. We enforce this with deny lists in `.claude/settings.json` and a `PreToolUse` hook via `block-credential-access.py` that intercepts both file reads and Bash commands. Dumping environment variables, decrypting AWS Secrets Manager, logging Lambda envs, or running `wrangler secret` commands get instantly blocked with a loud `[CRED-GUARD]` log. Plus, a tidy `.claudeignore` keeps build artifacts, caches, and upload folders out of the prompt window altogether. Safe, snappy, and stress-free!
Want to set up these environment-friendly guardrails yourself? You can simply ask your agent like this:
Separate Global Guidelines from Detailed Docs
`AGENTS.md` and `CLAUDE.md` serve as the default rulebooks that agents automatically reference when tackling project tasks. As your project grows, so does the mountain of context your AI needs to know—and before you know it, your global guidelines balloon into a massive, token-guzzling monster.
That’s why you should keep your global guidelines lean: stick strictly to the tech stack, non-negotiable security rules, core coding conventions, and pointers to domain-specific docs. Your agent just needs a quick map of what lives where, so briefly list each document's purpose, summary, and path. With this strategy, we keep our global guidelines comfortably trimmed down to just 100–200 lines.
The agent will then smartly decide whether a user’s prompt actually requires extra context and pull in only the files it needs for that session—saving your precious tokens (and your sanity!).
Run Lean with Custom Skills
Frequent, repetitive tasks—like committing, reviewing, opening Pull Requests, or handling Git operations—are best packaged into custom "Skills." Here at Videostew, we rely on handy shortcuts like `cm`, `rv`, `pull-request`, and `aws`. Skills do much more than just save a few keystrokes; they standardize repetitive workflows and allow you to refine your processes step by step.
We build and manage our skills based on two simple rules. First, build custom skills only when absolutely necessary. AI tends to be a bit verbose—whether writing code or documentation—so we steer clear of "one-size-fits-all" skills copied off the internet. Instead, we start with the simplest bare-bones version tailored to our goal, test it in the wild, and fine-tune edge cases as we go. Second, turn only high-frequency tasks into skills. Having too many skills can bog down session startup times and clutter recommendation lists, so for lower-frequency must-knows, we keep them neatly tucked away in separate documents inside `docs`.
At the end of the day, a "skill" is just another document your AI agent reads. Even a standalone `md` file can deliver results just as sharp as a specialized skill—as long as execution steps and decision criteria are clearly laid out. The real difference simply comes down to how often you use it, and how easily your agent can discover and invoke it.
All Your Infrastructure, Managed in One Place
Why juggle a dozen dashboards? By letting our AI agents handle recurring tasks and queries, infrastructure management becomes a breeze. Think AWS via the AWS CLI, Cloudflare powered by Wrangler, and Google Cloud driven by `gcloud`. Once the CLIs and authentication environments are wired up on the server, you no longer have to wander through labyrinth-like back offices and endless dropdown menus. Just tell the agent what you need in plain English, and it pinpoints the exact commands and workflows required. It can even pull traffic and cost metrics to help you forecast expenses on the fly (and prevent any surprise cloud bills!).
This is an absolute game-changer when working with AWS. While Cloudflare keeps things snappy and intuitive, navigating AWS’s massive jungle of granular services can be a full-time job. With an AI agent connecting the dots between related services and configurations, you don’t have to spend your weekend reading technical manuals—you can jump straight into building killer features for your video editing workflow.
Of course, with great power comes great responsibility! Because infrastructure changes directly impact live services, we enforce strict global guidelines and pre-flight checks: always confirm the objective, the exact modifications, and the impact scope before pulling the trigger. Measure twice, cut once!
Keeping an Eye on Everything: Frictionless Monitoring
Logs are a developer's best friend—essential for debugging in dev, and critical for performance tracking, analytics, and rapid customer support in production.
On dev servers, there’s no need to pump logs off-site, so we store both backend and frontend logs neatly in files. For the frontend, we hook into browser `console` methods to stream logs to a designated endpoint that writes straight to disk. The backend uses the framework's native logging path. The magic? The AI agent inspects errors directly during tests and fixes issues on the spot—saving you from endless manual copy-pasting from dev tools. It’s smarter, faster, and lets you focus on creating magic!
Behind the scenes of our online AI video editor, seamless rendering relies on rock-solid infrastructure! On production, client-side glitches take a detour through a dedicated collection layer (like AWS Lambda) straight into CloudWatch. Meanwhile, our backend scoops up framework errors via syslog and log agents, streaming them directly into CloudWatch Logs. We keep a centralized playbook—or a dedicated logging guide—documenting exactly which CloudWatch resource handles which log type and how to query them.
Here’s why this setup is an absolute game-changer.
By unifying error logs under CloudWatch, hunting down bugs feels identical whether they happen across multiple microservices or distributed Lambda functions. Even if each service spits out different logging formats and call stacks, centralized logging makes tracking issues a breeze. AI agents can effortlessly pinpoint the scene of the crime and cross-reference the relevant code!
Never Let an Issue Slip Through the Cracks
When developing alongside AI agents, codebases tend to branch out fast—think of it like editing a timeline with way too many video tracks. You start digging into Issue A, only to stumble upon hidden side quests: prerequisite blockers, or sneaky quirks that need post-launch log reviews. This is where we lean heavily on GitHub Issues.
To make tracking effortless, we set up a handy GitHub Issue command (like
/issue). Whenever a rabbit hole appears mid-development, we fire off the command to spawn a sub-issue on the fly. Then, we dive right back into Issue A without losing our groove. The branched issue stays safely parked so nothing gets forgotten. Staying laser-focused on one problem at a time also keeps our agent’s context window sharp—and saves precious tokens along the way!Let’s be real: code doesn't live in a vacuum. Once real-world user media and database quirks enter the mix, unexpected plot twists happen. Dummy data in dev environments won't catch everything, and non-fatal glitches can easily stay buried forever. That’s why, post-release, we spin up a
watchissue—or tag an existing one—complete with an observation window and review date. By dropping aDue:tag and handy labels right at the top of the issue body, tracking review cycles is seamless. When review day arrives, a quick prompt like “Let’s review overdue watch issues” lets us analyze real telemetry, verify the fix, and decide if the edit needs another cut.Keep Small Tasks Small, Big Tasks Big
As a scrappy startup, we can't afford to burn cash by pinging ultra-high-end AI models for every little question (our wallets can only take so much!). So, we are constantly hunting for the most efficient ways to deploy AI. In everyday coding and operations, a surprising amount of work boils down to quick checks: "verify this," "inspect that," or "let’s do X." Even before tackling a massive feature, we usually run a few lightweight exploratory passes first. That’s why our cost-effective default is always a solid mid-tier model (like Claude Sonnet, or Codex Terra).
Here’s the secret sauce: we set global instructions so that whenever a truly complex task comes up, the mid-tier model automatically delegates the heavy lifting by spawning a top-tier model as a sub-agent (like Claude Opus/Fable, or Codex Astra). This allows our default model to act as a smart router—balancing cost and performance by picking the right brain for the right job.
Delegation means the sub-agent analyzes the scope and sketches out the blueprint. Once the battle plan is ready, it hands it back to our default model to hammer out the actual code. It's not completely bulletproof, of course—delegation can cause a slight bottleneck, and occasionally the default model stubbornly tries to solve a PhD-level problem on its own and makes a mess.
The fix? Clear ground rules. We set global instructions to escalate whenever a task involves high complexity, security, authentication, or database schema changes—or simply when a task takes too long or balloons in scope. Keep the roles crystal clear: the main agent handles context injection, delegation, coding, and testing, while the sub-agent sticks to architecture and planning. Escalation triggers will vary from project to project, so fine-tune those thresholds as you test.
※ Fun tip for Claude users: you can use internal planning profiles (like 'opusplan') to seamlessly separate your general working model from your planning engine.
※ And yes—if we know right out of the gate that a task is an absolute monster, we skip the middleman and go straight to the heavy-hitter models.
A Fully Integrated, Living Manual
Refund policies, checklists for processing cancellations, account rules, basic ops knowledge... you name it. Internal service documentation is notoriously massive, and let’s be honest—it needs updates almost every time an edge case pops up. Plus, since the whole team touches it, you need a rock-solid version history without chaotic edit conflicts.
Our secret weapon? We turned our operational manual into its own Git repository, packed with clean Markdown (.md) files. The front door—our
README.md—acts as a master directory directing traffic to specific topics. Because this repo is authenticated via standard Git CLI or Git MCP and hooked straight into our AI agent as a skill (/manual), our team can look up or tweak docs on the fly without breaking a sweat.※ Pro-tip: A hierarchical document structure is our go-to pattern for both general guidelines and ops manuals. It’s an absolute lifesaver for cutting down token usage while keeping things hyper-efficient.
Other Handy Bits & Tricks
branch.mdoutlining its purpose, scope, and instructions—referenced by our global rules—so nobody (human or AI) loses the plot.--
We've outlined the broad strokes of our agent-centric dev and ops workflows today. In our next post, we'll dive into Token-Saving Tips for AI Agents (because your budget will thank you). Stay tuned!