
hhlee
2026-09-09 21:22:53
Behind
Setting Up the Dev & Ops Environment for Our Secret Agents 🚀
🗞️
[Update] From Generating Images to Remixing and Video Creation—All in One Place!
Just double-click any image in the editor, and boom! You can now jump straight into four powerful AI actions.Create a completely fresh image based on your slide...
🤔
Building an AI Agent from Scratch: Let's Demystify the Magic!
In our previous post, Smart Token-Saving Hacks for AI Agents, we explored quick tips to cut down on tokens right away. This time, we’re peeling back the curtain...
🤔
Smart Ways to Save Tokens with AI Agents (Without Losing the Magic)
Must be nice if your company covers your token bills, but for a scrappy startup like ours, token cost-efficiency (or simply surviving the invoice) is practicall...
🤔
Setting Up the Dev & Ops Environment for Our Secret Agents 🚀
At Stew, we're sharing how we set up and utilize our environment for agent-based coding (while continuously supercharging our AI video editor behind the scenes!...
🗞️
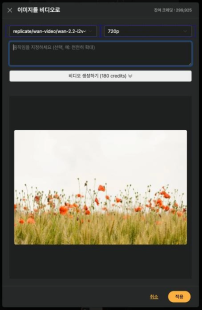
[Update] Give Stock and Uploaded Photos an AI Makeover with 'Generative Edit'
You can now refine and reuse the images you already have—no need to toss them out and start over. With the newly added 'Generate Edit' feature, the image curren...
🎓
Why You Pick a Shorts Template, Make Three Videos, Then Never Use It Again
Search for Shorts templates, and you’ll find an endless supply of free options. But after downloading one and making about three videos, many creators find them...
🎓
Automating shorts is easy—getting them consistently great every time is the real challenge
If you search for shorts automation, you’ll find endless workflow tutorials that promise everything at once: script generation, images, voiceover, even upload. ...
🎓
Before You Pick an AI Video Editor, Decide *What* You Actually Want to Make
When you read those “Top 5 AI video makers” listicles, they usually bundle all the trendy tools together, compare pros and cons, and highlight key features.But ...

At Stew, we're sharing how we set up and utilize our environment for agent-based coding (while continuously supercharging our AI video editor behind the scenes!). Because the AI landscape evolves at lightning speed—and honestly, our own workflow completely reinvents itself every 3 to 6 months—this post might come with an expiration date. Still, as long as the LLM paradigm holds steady, this should be a pretty handy peek behind the curtain. So, here’s a snapshot of how we get things done as of September 2026.
The key shift? We no longer treat AI agents as just another handy tool in the shed; they are now the primary interface where all work begins and ends. What matters most today is building an environment where AI has direct access and operational control across the board—development, testing, documentation, restricted DB access, logging, monitoring, and even customer support—empowering it to triage and execute tasks on demand.
※ Note: While this guide is written around agent CLIs, the underlying principles apply whether your agent lives on a desktop app or in a browser tab.
Remote Dev Servers & CLI Operations
We keep our codebase and CLI tools parked on a dedicated dev server, remoting in via SSH from laptops or even mobile devices. Tailscale handles secure access to the dev server and internal services. This frees us from being tied to a single machine, letting us dive into the exact same repo and runtime from anywhere. The biggest win? We run Claude Code (aka claude) or Codex CLI (aka codex) directly on the server and check real-time changes instantly. Plus, with a server running 24/7, spinning up scheduled tasks, automated workflows, and background routines is a total breeze.
Setting It on Autopilot
Bypassing permission prompts to let agents chain commands autonomously is affectionately dubbed "YOLO mode." In a remote dev sandbox, it’s an absolute game-changer for speeding through low-risk, well-scoped tasks—think recursive codebase searches, test suites, and log debugging—without babysitting every single keystroke.
Turning on bypass mode is like handing your AI agent the master keys—suddenly, its playground gets huge. But if it can touch production servers or live credentials, even a tiny hiccup can become a full-blown incident. That’s why we layer on solid guardrails: hooks that block sensitive files, confirmation checks before any AWS changes, and strict limits on Cloudflare credentials. Remember: streamlining approvals is great, but giving your AI a blank check? Not so much.
Supercharging File Search in Claude
While we might not manually @-mention files as often these days, smart file referencing is still a lifesaver. In our workflow, while Codex was surprisingly sharp at suggesting neat, short file paths, Claude’s default file search felt… well, a bit sluggish. So, we took matters into our own hands and configured a custom script for
fileSuggestioninside.claude/settings.json.This nifty script only scans files tracked by
git ls-files, prioritizing short paths and matching prefixes right away. If your search query is empty, it smartly pulls up your most recently modified files first. The upside? Finding project files is blazingly fast compared to the default search. The slight catch? Untracked files won't show up, and you'll needfzfpermissions or external dependencies set up.Locking Down Sensitive Data (No Leaks on Our Watch!)
Flipping the switch to bypass or full-on YOLO mode expands the horizon of what an agent can touch. Sure, it feels seamless, but convenience shouldn't cost you your security. If sensitive variables like your
.envfile sneak into a chat prompt, they’re out in the open. That’s why we stick to a strict, two-tier security playbook.First, our global rules explicitly forbid the agent from ever reading, printing, or sniffing around
.envfiles, AWS credentials, Cloudflare configs, private SSH keys, or token vaults. Files packing live secrets—like.env*,.aws/credentials,.cloudflared,.npmrc, andauth.json—are completely off-limits. Whenever sensitive values are needed, our team handles them directly, leaving the AI agent to focus purely on safe identity checks and public data lookups.Even if you set up global instructions, AI agents love to rebel. The moment they think it's necessary, they'll happily try sneaking a peek into your
.envfile. That’s why you need an automated safety hook to stop sensitive paths from slipping into your chat history. With a deny list in.claude/settings.jsonand aPreToolUsehook inblock-credential-access.py, you can intercept both file access and Bash commands. Risky maneuvers—like printing all environment variables, decrypting AWS Secrets Manager, dumping Lambda envs, or runningwrangler secret—are instantly blocked with a loud[CRED-GUARD]prefix in the logs. Don’t forget.claudeignoreeither: exclude env files, build artifacts, cache, and upload directories to keep unnecessary context from eating up your resources.Want to build these safety rails for your own workflow? You can simply ask your agent like this:
※ Chatting with non-devs who love "vibe coding," I've noticed security often takes a backseat. The vibe is usually: "Hey, the AI set up the database and handled deployment, so if it works, it works!" But here’s the catch: your secret keys should never, ever end up in your source repo or chat history. Even if it feels a bit old-school, manage your sensitive credentials manually via your terminal or a text editor. Let your AI agent know the environment variable names to get the job done—never the actual values!
Separating Global Instructions from Documentation
Files like
AGENTS.mdandCLAUDE.mdserve as the foundational handbook that agents automatically read before tackling tasks. As your project grows, the list of things your AI "needs to know" balloons too. If you’re not careful, your global instructions will turn into an endless scroll—and a prime culprit for devouring your token budget.Keep your global instructions lean and mean: stick to the tech stack, non-negotiable security protocols, core coding conventions, and a directory pointing to specialized docs. The agent just needs a map to navigate what lives where, so provide a crisp, one-line summary and location for each doc. Aim to cap your global guidelines between 100 to 200 lines—your context window (and wallet) will thank you.
The agent cleverly figures out whether your request actually requires loading extra files. By only fetching what's truly needed for the current session, it cuts down on unnecessary token waste (and saves precious digital energy!).
Running Custom Skills Like a Pro
Frequent tasks—like commits, code reviews, creating Pull Requests, and routine Git operations—are organized into custom "Skills." At Videostew, we rely on handy shortcuts like `cm`, `rv`, `pull-request`, and `aws`. These skills do way more than just save your fingers from extra typing; they lock in reliable, standardized workflows for repetitive tasks and let you refine them over time.
We create and manage these skills based on two golden rules. First, we build them in-house only when strictly necessary. AI has a funny habit of bloating code and docs if you let it, so we steer clear of "one-size-fits-all" skills grabbed randomly from the web. Instead, we start as lean as possible with just the core task in mind. As we run into real-world edge cases, we tweak, trim, and polish the skill until it perfectly fits our project. Second, we only turn high-frequency tasks into skills. Hoarding too many skills clutters session loading and recommendation menus! For low-frequency tasks that are still critical, we neatly tuck them away in dedicated `docs`.
At the end of the day, a skill is just another piece of documentation the agent reads. Even a standalone `md` file can produce identical results as long as the instructions and decision criteria are crystal clear. The real difference simply boils down to frequency: how often do you need it, and how easily do you want to summon it?
All-in-One Infrastructure Management
We've structured our infra management so that the agent handles most lookups and repetitive maintenance. We leverage the AWS CLI for AWS, Wrangler for Cloudflare, and the Google Cloud CLI (`gcloud`) for Google Cloud. With CLIs and authentication safely configured on the server, you no longer have to navigate a labyrinth of complex back-office dashboards. Just describe what you need in plain English, and the agent maps out the right commands and steps. It can even pull real-time traffic and cost metrics to help you forecast expenses before making a move.
This is especially handy when you're working with AWS. While Cloudflare’s dashboard is refreshingly clean and intuitive, navigating AWS can sometimes feel like wandering through a maze of endless, granular services and hidden options. Having an AI agent map out the relationships between different services and configurations takes the heavy lifting off your shoulders—so you can skip the deep-dive documentation rabbit hole and stay focused on what really matters: creating great work.
That said, because infrastructure changes directly impact your live service, it’s always smart to have guardrails. Make sure your global guidelines or related agent skills enforce a pre-check step before touching anything. Double-checking the goal, exact modifications, targets, and blast radius *before* hitting "apply" saves you from unintended downtime surprises!
Keep an Eye on Everything: Next-Level Monitoring
Logs are your lifeline—essential for debugging during development, and vital in production for troubleshooting, tracking metrics, and quickly resolving customer issues.
In the dev environment, there's no need to blast logs externally; saving backend and frontend logs directly to files works like a charm. On the frontend, you can hook into the browser's `console` methods to stream logs to a dedicated endpoint, which writes them right to a file. The backend simply sticks to the framework's native logging path. This lets your agent check test logs in real time and fix issues on the fly—saving you from the tedious chore of copying and pasting console errors!
In production, client-side errors get shipped through a tailored pipeline (like AWS Lambda) straight into CloudWatch. On the backend, syslog and log agents gather framework errors directly into CloudWatch Logs. Just keep a clear record in your global guidelines or docs showing which CloudWatch resources store each log type and how to query them.
Here’s why this setup rocks:
By centralizing error logs around CloudWatch, you can search and analyze everything in one unified way—even when your architecture is split across multiple servers and Lambda functions. Even if different services log differently or produce wildly unique call stacks, a single source of truth makes tracking bugs a breeze. Your AI agent can pinpoint the exact root cause, cross-reference the relevant code, and get you back on track in no time.
Never Miss a Beat: Smart Issue Management
When developing alongside AI agents, projects can branch out faster than a plot twist in a blockbuster movie. You dive into Problem A, only to uncover hidden roadblocks, prerequisites that demand attention first, or "fixed" bugs that require future log tracking. Whenever we hit this crossroad, we turn to GitHub Issues to keep our sanity intact.
To make this seamless, we created a dedicated GitHub Issue skill (`/issue`). Whenever a side quest pops up during development, we trigger the skill, log a derived issue on the fly, and dive right back into Problem A without skipping a beat. Nothing gets lost in the void, and every loose end eventually gets tied up. Plus, staying laser-focused on one task keeps the agent's context clean—saving precious tokens along the way!
Here’s the catch: code rarely lives in a vacuum. Once it meets real user data and production databases, unexpected gremlins can sneak in. Staged dummy data won't catch everything, and silent issues that don't trigger error logs could stay buried forever. Our solution? Once a feature is shipped, we spin up a `watch` issue with a set monitoring window and a review date—or tag an existing ticket with an observation plan. By slipping a simple `Due:` tag in the first line alongside custom labels, we keep track of when to revisit. Once the timer is up, we review the collected data to confirm if the fix actually held up or if it needs another round on the editing floor.
Keep Small Tasks Lean, Save Big Brains for Big Jobs
Let's be real—as a scrappy startup, we can't unleash top-tier frontier models for every single keystroke. Cost efficiency is our superpower. In day-to-day coding and ops, a huge chunk of work boils down to simple, repetitive checks: "verify this," "scan that," or quick status sweeps. Even before tackling massive refactors, we run lightweight reconnaissance. That's why we set reliable mid-tier models as our everyday default (think Sonnet for Claude, or Terra for Codex). It gets the job done brilliantly without burning through the runway!
To pull this off, we set up global instructions so our agent knows when to call in the "heavy artillery"—summoning a high-tier model as a sub-agent for heavy-duty tasks (think Fable for Claude, or Astra for Codex). This turns our base model into a smart router, striking the perfect balance by deploying the right AI brain for the right job.
Delegating tasks works like this: the sub-agent takes on scoping out the changes and drafting a rock-solid blueprint. Once it returns that battle plan, the base model rolls up its sleeves and gets down to the actual coding. Naturally, it’s not all sunshine and rainbows. The main trade-offs? You might hit occasional delegation bottlenecks, and sometimes the base model gets overconfident and botches a complex task it really should have passed off to the higher-tier model.
The fix? Fine-tune your global instructions! Instruct the agent to escalate whenever it senses complex logic, security, auth checks, or DB schema changes—or simply when a task takes too long and spirals in scope. Keep a crystal-clear division of labor: the main agent handles context injection, delegation, coding, and testing, while the sub-agent focuses purely on high-level planning. Escalation triggers vary across projects, so feel free to tweak these thresholds on the fly as you see how your AI performs in the wild.
※ Fun fact for Claude users: there’s a hidden gem model called 'opusplan' that lets you neatly split models between your standard environment and dedicated planning mode.
※ And of course, if a task screams "danger zone" right from the start, we just kick things off with a high-tier model from square one!
A Fully Unified Operations Manual
Refund policies, prerequisites for processing payouts, account security, day-to-day operations... internal company manuals are absolute behemoths. Worse, they need constant updates every time a wild edge case pops up. Since the whole team contributes, tracking version history cleanly without merge chaos is non-negotiable.
Our solution? We manage our entire ops manual in a dedicated Git repository packed with clean Markdown (.md) files. The
README.mdserves as the central directory, acting as a gateway that directs readers to the right documentation files across every operational domain. We hooked this repo directly into our agent environment via standard Git CLI or Git MCP integrations using a custom skill (/manual). Now, our AI agents can look up guidelines or push manual updates in a snap, keeping our video editing engine running smoothly around the clock.※ Hierarchical document structures are a recurring pattern we swear by—whether for general guidelines or operational manuals. It’s an incredibly efficient way to keep things structured while giving your precious token budget a much-needed break!
A Few More Things to Note
--
That wraps up our high-level overview of running an agent-driven dev and ops setup! Up next, we're sharing some handy Token-Saving Tips for AI Agents. Stay tuned!