
hhlee
2026-09-09 21:22:53
Behind
Setting Up the Ultimate Dev & Ops Playground for Our Secret Agents
🗞️
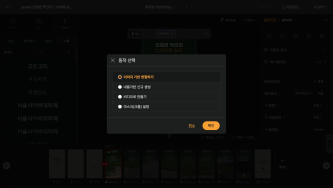
[Update] From Generating Images to Remixing and Video Creation—All in One Place!
Just double-click any image in the editor, and boom! You can now jump straight into four powerful AI actions.Create a completely fresh image based on your slide...
🤔
Smart Token-Saving Hacks for AI Agents (Without Losing the Magic)
Must be nice if your company covers your unlimited token expenses, but for a hungry startup like ours, token cost-efficiency (aka that terrifying monthly invoic...
🤔
Setting Up the Ultimate Dev & Ops Playground for Our Secret Agents
Here at Stew, we want to give you a behind-the-scenes look at how we set up and navigate agent-based coding. In the AI world, things move at lightning speed—hon...
🗞️
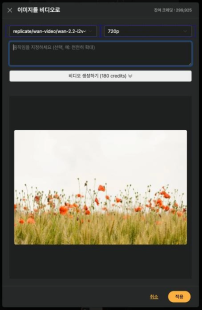
[Update] Give Stock and Uploaded Photos an AI Makeover with 'Generative Edit'
You can now refine and reuse the images you already have—no need to toss them out and start over. With the newly added 'Generate Edit' feature, the image curren...
🎓
Why You Pick a Shorts Template, Make Three Videos, Then Never Use It Again
Search for Shorts templates, and you’ll find an endless supply of free options. But after downloading one and making about three videos, many creators find them...
🎓
Automating shorts is easy—getting them consistently great every time is the real challenge
If you search for shorts automation, you’ll find endless workflow tutorials that promise everything at once: script generation, images, voiceover, even upload. ...
🎓
Before You Pick an AI Video Editor, Decide *What* You Actually Want to Make
When you read those “Top 5 AI video makers” listicles, they usually bundle all the trendy tools together, compare pros and cons, and highlight key features.But ...
🤔
Before you get a quote for one AI video, ask yourself this: "How many times will I want to repeat this?"
The first message we usually get from people asking about AI video outsourcing is almost always the same. It all boils down to one question: “How much is it?” I...

Here at Stew, we want to give you a behind-the-scenes look at how we set up and navigate agent-based coding. In the AI world, things move at lightning speed—honestly, our own workflow completely shifts every 3 to 6 months! So while this post might have an expiration date, we believe our current setup offers valuable insights (unless the whole LLM paradigm flips overnight, of course). Consider this our tech snapshot of how we get things done as of September 2026.
The secret sauce? We don't treat AI agents as just another handy tool in our belt. Instead, they serve as the alpha and omega—the central interface where virtually all our work begins and ends. The real game-changer is building an ecosystem where AI can tap into and operate across every stage: development, testing, documentation, restricted DB queries, logging, monitoring, and even customer support. Handing off and orchestrating these tasks seamlessly has become our ultimate superpower.
Running Remote Dev Servers & CLI Tools
We keep our codebase and CLI tools parked on remote development servers, connecting on the fly via SSH from our laptops—or even our phones when inspiration strikes! We secure access to our dev servers and internal services using Tailscale. This means we're never tied down to a single physical machine; the exact same repo and runtime environment are ready whenever and wherever we are. Running Claude Code (or simply 'claude') and Codex CLI directly on the server lets us review code changes instantly. Plus, with servers humming 24/7, setting up scheduled routines, recurring jobs, and heavy automation is an absolute breeze.
Letting AI Take the Wheel: The YOLO Mode
Skipping approval prompts to run sequential commands without babysitting is what the cool kids call "YOLO mode" (or the
bypass permissionsapproach). It's a lifesaver for tearing through low-risk, well-defined tasks like repetitive searches, test runs, and log scraping at full throttle.Of course, going full auto means the agent has a wider playground—and if it gains access to production servers or sensitive credentials, a small slip-up could turn into a major plot twist. That's why we install rock-solid guardrails: pre-commit hooks to block sensitive files, mandatory confirmation checkpoints before touching AWS infrastructure, and strict boundaries around Cloudflare credentials. Remember: streamlining the approval process doesn't mean giving the AI a blank check. Keep it fast, but keep it smart!
Supercharge Your File Search in Claude
While we might not be @-mentioning files all day like we used to, quick file referencing is still an absolute lifesaver. In our workflow, we noticed that while Codex nails those clean, short file path suggestions, Claude’s default search can feel a little... sluggish. So, to keep our momentum going, we configured a custom script for `fileSuggestion` right in `.claude/settings.json`.
This nifty script only searches files tracked via `git ls-files`, putting filenames and concise paths front and center. If your search query is empty, it smartly pulls up your recently modified files first. It lets you jump to project files way faster than the default setup! Just a quick heads-up: untracked files won't show up in the suggestions, and you'll need permissions to install external dependencies like `fzf`—but the speed boost is totally worth it.
Locking Down Sensitive Data (Because Safety First!)
When you're running in bypass or full-on YOLO mode, your AI agent suddenly gets the keys to a much wider kingdom. Sure, it feels seamless, but convenience shouldn’t come at the cost of security. If sensitive environment variables like your `.env` leak into the chat context, game over. That’s why we enforce a strict, two-tier security shield.
First, our global instructions strictly forbid the agent from ever reading or spitting out `.env` files, AWS credentials, Cloudflare configs, private SSH keys, or token vaults. Files packed with real secrets—like `.env*`, `.aws/credentials`, `.cloudflared`, `.npmrc`, and `auth.json`—are strictly off-limits. Whenever a key is needed, the user checks it manually, while the agent sticks strictly to public info or non-sensitive identity checks.
Let’s be real, though: even with the best prompts, agents can be rebellious. If an agent thinks it "needs" that config to solve a problem, it might try snooping anyway. That's why we back prompt rules with hard mechanical guardrails. We pair the deny list in `.claude/settings.json` with a `PreToolUse` hook via `block-credential-access.py` to inspect every file access and Bash command. Commands that try to dump all environment variables, decrypt AWS Secrets Manager, print Lambda variables, or invoke `wrangler secret` get shut down instantly—tagged with a crisp `[CRED-GUARD]` in the logs. We also trim down `.claudeignore` to filter out env files, build artifacts, and cache/upload directories so our context window stays squeaky clean and rock-solid secure.
If you’d like to set up these eco-friendly rules yourself, here’s how you can prompt your AI agent.
Separate Global Instructions from Detailed Docs
`AGENTS.md` and `CLAUDE.md` serve as the default rulebooks that your AI automatically reads before jumping into project tasks. As your project grows, so does the mountain of background info your AI needs to digest. If you aren't careful, your global instructions will balloon into an endless novel—becoming the prime culprit that melts away your tokens (and budget!).
That’s why global guidelines should only cover the absolute essentials: the core tech stack, non-negotiable security protocols, key coding rules, and a lightweight map pointing to domain-specific docs. Your agent still needs to know what lives where, so simply include a brief summary, purpose, and file path for each document. Following this rule of thumb keeps our global instructions lean and mean—aiming strictly for 100 to 200 lines.
By doing this, the agent determines on the fly whether your prompt requires loading extra files, pulling in only what is strictly necessary for the active session. No fluff, no wasted tokens!
Running Custom Skills Like a Pro
Frequent, repetitive tasks—like committing, code reviews, opening PRs, or routine Git operations—are grouped into dedicated "skills." At Videostew, we rely on snappy shortcuts like `cm`, `rv`, `pull-request`, and `aws`. These skills do way more than just save a few keystrokes; they lock in standardized procedures and allow us to refine them over time.
We build and manage our skills around two core principles. First, build them in-house, only when truly needed. AIs have a knack for over-engineering and bloating both code and docs, which is why we avoid copy-pasting "do-it-all" skills straight from the internet. We always start with the simplest bare-bones version tailored to our specific workflow, polishing edge cases and rules through hands-on daily use. Second, only turn high-frequency tasks into skills. Having too many skills clutters the initial session loading and overwhelms recommendation menus. For low-frequency tasks that are still critical, we simply document them separately under `docs` instead.
At the end of the day, a "skill" is just another document your agent reads. Even with a simple, standalone `md` file, as long as you spell out the execution steps and decision criteria clearly, the final results won't look much different from a polished skill. The real difference simply boils down to how often you use it, and how easily your agent can discover and trigger it on the fly.
Streamlining Infrastructure Operations in One Place
When it comes to managing the heavy lifting of infrastructure, we let our agents handle the lion's share of routine queries and repetitive tasks. We tap into the AWS CLI for AWS, Wrangler for Cloudflare, and `gcloud` commands via the Google Cloud CLI for Google Cloud. Once the CLIs and authentication environments are wired up on the server, you can kiss goodbye to getting lost in labyrinthine admin dashboards. Just tell the agent what you need in plain English, and it figures out the necessary commands and procedures—even estimating upcoming bills based on real-time traffic and cost metrics along the way! 💡
This is a total lifesaver, especially with AWS. While Cloudflare’s dashboard keeps things refreshingly clean and intuitive, AWS is an intricate universe with endless micro-services, toggles, and menus that eat up your time. Having an agent navigate how these services and configurations interconnect frees you from cramming documentation on every new tool, letting you pour that energy back into building great features.
Of course, with great power comes great responsibility—infrastructure tweaks directly impact live production! That’s why you always want strict safeguard prompts or skill-level confirmation steps baked in before anything changes. The agent must clearly surface the objective, proposed edits, target resources, and potential blast radius before pulling the trigger.
Keeping Eyes on Every Single Detail
Logs are a developer's best friend during development for debugging, and on production servers, they're the ultimate lifeline for troubleshooting, metrics, and saving the day when customers hit a snag.
In local development environments, there's no need to blast logs out to external services; keeping both backend and frontend logs stored as local files works wonders. For frontend logs, we hook into browser `console` methods and route them to a dedicated logging endpoint that writes to a file, while the backend relies on standard framework logging. This means the agent can instantly inspect test-run logs, spot issues, and patch fixes on the spot—so you don’t have to waste time copy-pasting terminal lines back and forth. Smooth, seamless, and smartly automated! 🚀
On our production servers, client-side errors take a dedicated pipeline straight into a collection layer like AWS Lambda before being safely tucked away in CloudWatch. Meanwhile, our backend pipelines framework hiccups into CloudWatch Logs using syslog and custom log agents. We make sure to document exactly which CloudWatch resource holds what—along with handy retrieval recipes—in our global engineering guide (so nobody gets lost in the data wilderness!).
Here’s how we put this superpower to work:
By centralizing error logs around CloudWatch, troubleshooting feels seamless, even when video processing tasks are scattered across multiple microservices and serverless functions. Regardless of differing logging formats or funky stack traces, a single source of truth makes it a breeze for our debugging agents (and human devs!) to pinpoint root causes and compare them directly with the codebase.
Flawless Issue Tracking (No Bugs Left Behind)
When you're building next-gen AI video editing tools alongside autonomous agents, development rabbit holes are bound to happen. You start digging into Issue A, only to stumble upon hidden edge cases, prerequisite roadblocks, or little quirks that demand extra observation later. Whenever that happens, we lean heavily on GitHub Issues.
We even wired up a dedicated shortcut skill (
/issue) so we can summon GitHub Issues anytime without skipping a beat. The moment a distraction pops up, we trigger the command, spawn a child issue, and swiftly pivot right back to crushing the original task A. No forgotten to-dos, zero context drag. Plus, staying laser-focused keeps our AI agent’s context lean—saving precious tokens and sanity along the way!Let’s be real: plenty of bugs don't surface from pure code alone. They show up when mixed with unique user uploads, complex video timelines, or production databases. These elusive quirks rarely pop up with boring dummy data, and if they don't throw a flashy error code, they could stay buried forever. Our solution? Once a patch is shipped, we create a dedicated
watchissue or append a monitoring roadmap to the ticket with set check-in dates. Using lightweight metadata likeDue:right on the first line paired with custom tags keeps verification on schedule. When the timer dings, we review the real-world metrics together and confirm whether the fix is truly rock-solid or needs one more tweak. That’s how we keep your editing flow butter-smooth!Small Tasks Stay Small, Big Tasks Go Big
As a scrappy startup, our wallets can't handle blasting high-tier AI models for every single request 💸. That's why we spend a lot of time obsessing over efficiency. When handling everyday dev and ops tasks, you'd be surprised how much of the work boils down to quick checks: "verify this," "inspect that," or "run this quick test." Even before diving into a heavy feature, we usually run several lightweight sweeps just to get the lay of the land. With this in mind, we default to cost-effective mid-tier models (think Sonnet for Claude, or Terra for Codex).
To make this work seamlessly, our global system prompt instructs this default model to act like a smart router: whenever it sniffs out a truly hardcore task, it summons a high-reasoning sub-agent and delegates the heavy lifting (like calling Opus/Fable for Claude, or Astra for Codex). This keeps our workflow balanced, matching the right brainpower to the right job.
Here’s how delegation works in practice: the mid-tier model tasks the sub-agent with mapping out the scope and drafting a rock-solid plan. Once the sub-agent hands over the blueprint, our default model gets back to doing the actual hands-on coding. Is it completely foolproof? Not quite. You can hit minor latency bottlenecks during delegation, and occasionally the mid-tier model gets a bit overly confident and tries to tackle high-dimensional problems on its own—usually with chaotic results 😅.
The fix? Clear ground rules. We configure our instructions to mandate delegation whenever high-difficulty tasks, security, authentication, or DB schema changes are detected—or if a task takes too long and blows up in scope. Keep a strict separation of duties: the main agent handles routing, context injection, actual coding, and testing, while the sub-agent owns the deep planning. Every project has its own quirks, so feel free to tweak these escalation thresholds as you go.
※ Pro tip for Claude users: with custom workflows (or tools like 'opusplan'), you can cleanly split your planning engine from your everyday execution environment.
※ Naturally, if a task screams "danger zone" from minute one, we cut the middleman and launch straight into the powerhouse models.
A Fully Integrated Knowledge Hub
Refund guidelines, checkout checklists, account policies, everyday operational know-how… internal documentation gets massive fast. It demands constant updates every time a fresh edge case pops up. Plus, since everyone pitches in, keeping a clean edit history without painful merge conflicts is an absolute must.
Our solution? We turned our entire operations manual into a dedicated Git repository packed with Markdown files. The front door—our
README.md—acts as a clean directory mapping out which file governs what. By authenticating this repo via standard Git CLI or Git MCP and wiring it up as an AI skill (/manual), our team and AI agents can look up guidelines or tweak them on the fly, right inside our workflow.※ Hierarchical documentation isn't just for general guidelines; we lean on it constantly across our operational playbooks. It's our secret weapon for slashing token usage while keeping things hyper-efficient.
A Few Pro Tips & Field Notes
branch.mdto define the branch's goal, scope, and rules—letting global guidelines reference it seamlessly until the job is done.--
That wraps up our high-level overview of agent-centric development and operations! In our next post, we'll dive into Clever Token-Saving Hacks for AI Agents. Stay tuned!