
hhlee
2026-09-11 10:11:16
Behind
Smart Ways to Save Tokens with AI Agents (Without Losing the Magic)
🗞️
[Update] From Generating Images to Remixing and Video Creation—All in One Place!
Just double-click any image in the editor, and boom! You can now jump straight into four powerful AI actions.Create a completely fresh image based on your slide...
🤔
Demystifying AI Agents: Building One from Scratch (No Magic Wand Needed!)
In our previous post, Smart Token-Saving Hacks for AI Agents, we explored actionable ways to slash token usage right away. Today, we're diving under the hood to...
🤔
Smart Ways to Save Tokens with AI Agents (Without Losing the Magic)
Must be nice if your company covers your token bills, but for a scrappy startup like ours, token cost-efficiency (or simply surviving the invoice) is practicall...
🤔
Setting Up the Ultimate Dev & Ops Playground for Our Secret Agents
Here at Stew, we want to give you a behind-the-scenes look at how we set up and navigate agent-based coding. In the AI world, things move at lightning speed—hon...
🗞️
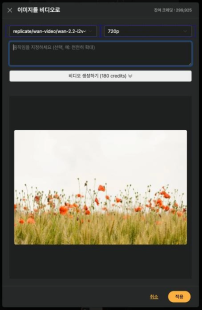
[Update] Give Stock and Uploaded Photos an AI Makeover with 'Generative Edit'
You can now refine and reuse the images you already have—no need to toss them out and start over. With the newly added 'Generate Edit' feature, the image curren...
🎓
Why You Pick a Shorts Template, Make Three Videos, Then Never Use It Again
Search for Shorts templates, and you’ll find an endless supply of free options. But after downloading one and making about three videos, many creators find them...
🎓
Automating shorts is easy—getting them consistently great every time is the real challenge
If you search for shorts automation, you’ll find endless workflow tutorials that promise everything at once: script generation, images, voiceover, even upload. ...
🎓
Before You Pick an AI Video Editor, Decide *What* You Actually Want to Make
When you read those “Top 5 AI video makers” listicles, they usually bundle all the trendy tools together, compare pros and cons, and highlight key features.But ...

Must be nice if your company covers your token bills, but for a scrappy startup like ours, token cost-efficiency (or simply surviving the invoice) is practically an everyday obsession. Sure, top-tier models understand you like mind readers and deliver breathtaking results—no debate there. But we are constantly racking our brains over one question: How can we get way more work done with much cheaper models?
How the Bill Actually Adds Up
The cost of the LLMs powering our AI agents basically boils down to this simple formula:
Unit Price per Token (Model) x Number of Tokens (Input + Output) = Total Cost
Most folks already know that the price per token varies wildly from model to model. And you probably also know that token count roughly scales with word count.
The real kicker, though, is how those tokens actually get counted... You might think, "Easy peasy, short question plus short answer equals low cost, right?" Well, if only it were that simple! The catch lies deep within how LLMs actually tick. To put it bluntly: an LLM has no consciousness, builds no rapport, knows zero about you, and has never heard of your project. It simply tokenizes text, feeds it through the model, and spits out the most probable continuation. That's it.
So, to make collaboration feel magically seamless, AI agents quietly bundle everything—the environment, project details, and every single thing you said two seconds ago—and ship it back to the model with every new prompt. It’s not just your latest follow-up question going through the wire. If you started off chatting about the weather, wandered into silly banter, pivoted to coding, and then shifted to marketing strategies... surprise! Even while hashing out your marketing campaign, that initial weather chat (and the AI's reply to it) is still being sent over again. Every single time.
Here's a quick way to visualize the tokens piling up per round of Q&A:
To make it even more realistic, it looks something like this:
This entire mountain of back-and-forth baggage riding along with every single request? That’s what we call Context.
To be fair, modern AI agents are getting pretty clever. They compress context, prioritize recent chats, and use prompt caching to shave down the bill. But here's the plot twist: context compression itself requires summarization—which is another computational task, and definitely not free. We'll dive deeper into that in a bit. But fancy optimizations aside, this is essentially the underlying dynamic behind every AI conversation you have.
That's why some people—dreading the thought of repeating themselves in a "New Chat"—keep piling task after task into a single chat window until the scrollbar screams for mercy. Sure, you'll still get answers, but you're also burning through a mountain of tokens you really didn't need to waste.
Here, we optimize and trim down this context in a few smart ways. You don't need to stop and obsess over "Wait, how heavy is this session's context right now?" every single time. It's really about picking up a few core habits and letting them run on autopilot.
Supercharging Your Prompt Cache
Now that we've covered the basics, here's the good news: modern AI providers don't tokenize and recalculate everything from scratch on their servers every time. Once a conversation is active, the AI simply builds on the calculations it already made, delivering faster and far more efficient responses. This is known as prompt caching. Even better, cached prompts come at a massive discount compared to raw, from-scratch computations. "Wait, so can I just keep chatting without a care in the world?"
Not so fast—there's a catch. Prompt caching can be a bit picky about when it kicks in. Usually, requests need to happen within a tight 5-minute window, the AI model or reasoning depth can't change mid-stream, and the system's memory or global instructions must remain untouched. Tweak just one of these, and boom—the AI computes the entire context from scratch again, right along with the full price tag.
Flip that around, though, and it means the perks are yours for the taking if you stay within those sweet spots! If you're orchestrating multiple agents across different creative tasks, a great trick is to review things briskly and fire off your next prompt before the cache expires—wrapping up your work smoothly without breaking the streak.
Put this together with what we talked about regarding context: when you switch topics entirely, start a fresh session to dodge context bloat and wasted cache. But while you're deep in the creative flow on the same topic, keep the momentum going without long pauses so that cached magic stays alive. That's the secret sauce!
Splitting Off Side Quests
When you're deep in the zone, issues rarely exist in isolation. The backend, auth, user data, UI, test suites, and that other feature hanging on for dear life are all tangled up together. In the old days, you might have happily coded in blissful ignorance. But modern AI agents? They love pointing out every tiny bug they spot along the way. That's when the itch strikes: "It's just a quick fix, let me tweak it real quick and get back to work." Don't take the bait!
In moments like this, be ruthless: peel off those side quests and keep your laser focus on the main mission. This keeps your context clean, stops useless info from cluttering your workspace, and saves those precious tokens. Plus, capturing those side issues right away ensures none of them slip through the cracks later.
Here is how that workflow looks in practice:
There are plenty of ways to sideline these distractions. You can simply stash them in a scratchpad
.mdfile, or do what we do and sync them directly with GitHub Issues. By establishing a quick, standardized logging habit (summarizing the current context, potential pitfalls, etc.), you can tackle the main challenge first—and then dive into those side quests later in a completely fresh, clutter-free session.Hierarchical Documentation: Keep It Neat, Keep It Lean
As we mentioned in a previous post, whether it's user manuals or global system instructions, nearly all documentation thrives on a hierarchical structure. Imagine dumping 1,000 lines of security, billing, ops, coding, and testing rules into a single global prompt. Sure, it'll work. But it also dumps a mountain of irrelevant data into your current session, burning through tokens like there's no tomorrow.
Instead, keep your global guidelines lightweight and essential, while delegating domain-specific details to dedicated sub-documents. The secret sauce? Never leave those sub-documents stranded! Always include clear pointers in your entry document (the global instructions) showing exactly where to find the deep-dive details when needed.
Here's a quick example of how you can set it up:
AI agents come equipped with a superpower called tool calling, allowing them to track down the extra info they need on their own. First, the agent checks the essential global instructions. If the task at hand requires digging into extra documentation, it smartly pulls up only those specific files. The result? The agent accesses just the bare minimum it needs to get the job done—saving you a sweet chunk of wasted tokens in the process.
Here’s the catch: using tool calling to read documents still burns turns and tokens, and once something is read, it sticks around in the context window for the rest of the conversation. Our golden rule? Frequency matters. Keep what’s needed "almost every time" right in the entry document, and stash the "once-in-a-while" info into external files. For the ultra-rare references, tuck them away in
/docsand summon them with a quick mention only when duty calls.Tidying Up Memory Instructions (Spring Cleaning for Your AI)
When you give strong commands or run into repeated hiccups, the AI agent often suggests or automatically saves new memory instructions. Translated: this memory prompt will hitch a ride on every single future conversation. While global guidelines live in plain text and are easy to track via commits, unmonitored memory instructions can pile up silently—becoming the ultimate hidden token drain.
Let everyday useful notes do their thing, but when it’s time to put your global instructions on a diet, do a quick maintenance run! Promote frequently used, high-value memories into the global guidelines, and ruthlessly delete the one-hit wonders you haven’t needed in weeks.
Divide and Conquer: Router Models vs. Flagship Models
Let’s be real: working with heavyweight flagship models (like Fable or Astra) feels like magic. You barely type a prompt, and boom—it gets your vibe, avoids dumb mistakes, and delivers spot-on video edits. But let’s not forget: top-tier smarts = top-tier costs. Time to get strategic!
When you run an agent-based workflow, nearly half the daily grind consists of routine tasks: parsing standard files, searching, tool calling, minor tweaks, or checking logs. That’s why we use a reliable, mid-tier workhorse (like Sonnet or Terra) as our default driver, setting up an automatic handoff to the heavyweight model only when the heavy lifting begins. In short? Your base model acts as the ultimate smart router—keeping your workflow blazing fast and your budget happily intact.
Mid-tier models might not be able to solve every problem on their own, but they’re definitely smart enough to gauge whether a task is a walk in the park or a complex puzzle. In fact, they’re clever enough to realize, "Hey, I thought this was simple, but it's actually getting pretty messy!" Sure, if you only need traffic routing, an ultra-lightweight model could do the trick. But since we need our model to handle a fair share of actual work in addition to routing, mid-tier models hit that absolute sweet spot.
This is where the magic of AI agents comes in with a feature called sub-agents. Just like how we open a fresh new chat tab, an agent can spin up its own mini-sessions, delegate tasks to them, and collect the final answers. Since an active session can’t just swap its own brain (underlying model) mid-conversation yet, delegating to sub-agents is our clever, battle-tested workaround.
And honestly, using sub-agents brings perks way beyond just swapping models on the fly. Even if a sub-agent has to dig through dozens of video assets or project files and goes through multiple rounds of trial and error, all that messy tool-calling clutter stays contained inside that sub-agent. Only the neat, polished conclusion gets delivered back to your main session! It’s the ultimate "keep the drama off the main stage" approach—keeping your primary context clean, fast, and focused.
We can set up a global instruction along the lines of: "If a task feels heavy, high-difficulty, or touches sensitive project logic, call in a high-performance sub-agent, hand over the context, and delegate the planning. Wait for the sub-agent's response, and once the blueprint is ready, execute the edits as guided." As you fine-tune these instructions in real-world use, you’ll find that sweet boundary of when to handle things directly and when to bring in the big guns. That way, you don’t have to micromanage every single prompt—your go-to model stays steady, and the right brain steps in automatically right when you need it.
Go Subscription, Every Single Time
Most API plans hit you with pay-as-you-go pricing, where every token counts. On the flip side, subscription models might have set tier limits, but those limits are insanely generous compared to standard pay-as-you-go rates. Providers likely offer this because tiered pricing helps build brand loyalty (and benefits from unused quota breakage), but for power users like us creating non-stop content? It's the ultimate cost-saving hack!
If you're dealing with standardized bulk tasks rather than interactive chats (think batch-classifying or summarizing hundreds of files at once), look into Batch API processing outside of your standard subscription. It often slashes costs by up to 50% compared to standard pay-as-you-go rates—talk about an easy budget win!
Many CLIs also feature a one-off execution mode where token consumption is baked right into your subscription plan (a handy trick you'll definitely want to lean on for custom skills later).
This opens up massive creative freedom for developing skills. For instance, when running a code review skill, you can summon a completely independent model to spark a lively peer-review debate and cross-validate the results. Sure, you could build this via regular API calls, but the real secret sauce is routing that heavy lifting through your subscription quota to get the absolute biggest bang for your buck.
Wrapping Up
And there you have it—practical game plans to harness top-tier AI models without making your wallet cry. Here’s the quick cheat sheet:
In our next post, we’ll dive into Building AI Agents from Scratch to Truly Understand How They Work. Once you see the internal engine running under the hood, all these token-saving hacks will click instantly—and you’ll be orchestrating AI like a pro. Stay tuned!